Making Analytics Work in Industrial IoT: From Streams to Strategy
@analyticssite
October 30, 2026 · 7 min read
I spent a decade watching industrial teams pour money into analytics platforms that promised everything and delivered little. The symptoms were always the same: dashboards that looked beautiful but answered questions nobody asked, data lakes that turned into data swamps, and a nagging feeling that all that sensor data should be telling us something useful. The problem was never the math. The problem was the data plumbing.
In industrial settings, the gap between raw sensor data and actionable insight is wide and treacherous. A temperature reading from a kiln, a vibration signal from a pump, a pressure spike in a pipeline, each piece of operational data arrives in its own format, on its own schedule, with its own quirks. If you try to force that chaos through a traditional ETL pipeline into a data warehouse, you end up with stale, brittle reports that break the moment you add a new sensor type. Real-time analytics demands a different approach.
Why Traditional Analytics Falls Short in the Factory
The standard business intelligence playbook was built for structured data: sales transactions, customer records, quarterly financials. You extract, transform, load, and then query. That works fine when your data changes slowly and your questions are predictable. But industrial IoT generates streaming data, hundreds or thousands of events per second from each machine. By the time you batch-load that into a data warehouse, the moment for action has passed. A predictive maintenance model that runs on last week's data is better than nothing, but it misses the slow drifts and sudden spikes that tell you a bearing is about to fail.
Event-driven architecture is the logical countermove. Instead of polling a database every five minutes, you subscribe to a stream of events as they happen. Apache Kafka has become the backbone for this approach in many factories. It decouples data producers, sensors, PLCs, edge computing nodes, from data consumers, which can be anything from a digital twin simulation to a dashboard for plant operators. The events themselves become the single source of truth, and analytics becomes a process of listening and reacting rather than querying and waiting.
Data Governance at the Edge
One of the trickiest lessons I learned was that you cannot impose perfect data quality at the source in an industrial environment. Sensors drift, networks drop packets, and maintenance crews occasionally unplug the wrong cable. If you reject every event that does not meet a strict schema, you will miss critical signals. On the other hand, if you accept everything without validation, your analytics degrade into noise.
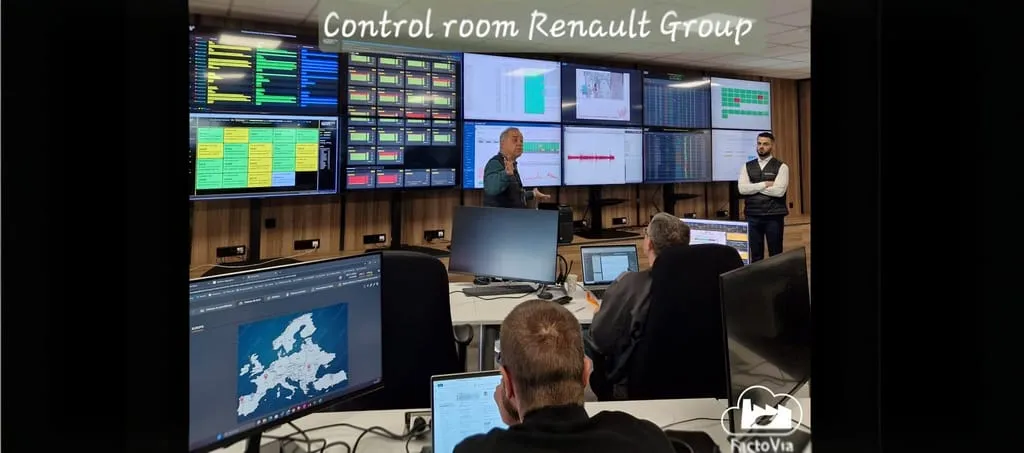
The solution I have seen work best is a layered data governance model. At the edge, you enforce basic rules, timestamps must be present, values must be within physical ranges. Downstream, in the Unified Namespace, you apply richer transformations: aligning units, filling gaps with interpolation, tagging events with context like machine ID and production shift. The key is that you never lose the raw event. If a downstream model needs to reprocess historical data, it can go back to the original stream. This approach preserves data quality without sacrificing the immediacy that makes real-time analytics valuable.
The Role of Time-Series Databases and Data Fabrics
A standard relational database is a poor fit for industrial sensor data. Every write is a row insert, and every query over a time range scans too many rows. Time-series databases, purpose-built for timestamped data, compress and index streaming data efficiently. They let you ask questions like "What was the average vibration amplitude on motor 7 over the last hour?" in milliseconds, even when you have billions of data points.
But a time-series database alone does not solve the integration problem. Factories run dozens of systems, MES, SCADA, CMMS, ERP, each with its own data model and access pattern. A data fabric, built on an event-driven backbone, ties these systems together without forcing them to converge on a single schema. The Unified Namespace acts as the semantic layer: every piece of operational data, from a temperature reading to a work order status, gets a consistent name and structure when it enters the fabric. Downstream tools, dashboards, ML models, digital twins, consume that normalised view without caring about the source system's quirks.
Predictive Maintenance and the Smart Factory Payoff
Predictive maintenance is the classic use case that gets everyone excited, and for good reason. When you have streaming data from hundreds of sensors on a critical machine, a model that flags an anomaly two hours before a failure can save a shift of production. I worked with a plant that used vibration and temperature streams from a compressor train. They built a simple model that compared current readings to a rolling baseline. When the deviation crossed a threshold, it triggered an alert. The system caught a bearing failure three times in the first month. Each catch avoided a four-hour downtime event worth roughly $50,000 in lost output.
The subtlety that many vendor demos gloss over is that predictive models degrade over time. Machines wear differently, process conditions change, and sensors get replaced with different models. A model that worked perfectly in April may be useless by October. The only way to keep it relevant is to continuously feed it fresh streaming data and retrain it. That requires an analytics pipeline that can handle versioned models, automated retraining triggers, and a feedback loop where maintenance records are fed back into the training set. It is not a set-it-and-forget-it proposition.
Manufacturing Analytics Beyond the Dashboard
Dashboards are useful for awareness, but they rarely drive action on their own. The real value of manufacturing analytics comes when insights are embedded into operational workflows. For example, a digital twin of a production line can simulate the effect of a schedule change before you make it. If the twin shows that rerouting work through cell 3 will cause a bottleneck, the system can suggest an alternative. That kind of what-if analysis depends on a unified, real-time view of the entire line, not just sensor data, but also order queues, inventory levels, and shift schedules.
Event-driven architecture makes this feasible because every change, a part entering a station, a temperature rising, a worker logging a break, is an event that the digital twin can consume and react to. The twin does not have to poll a database; it responds to the stream. This reduces latency from minutes to milliseconds and keeps the simulation state tightly coupled to reality.
Edge computing plays a crucial role here, too. Some decisions need to happen faster than the round trip to a central server allows. If a safety interlock trips, the machine must stop immediately. That logic belongs on the edge. But the event, "interlock tripped at 14:23:05", should still flow into the streaming data platform for aggregate analysis. The edge handles real-time control; the central system handles analytics over longer windows and across the whole plant. Splitting responsibilities this way avoids the trap of trying to run everything in one place.
Trade-offs and Practical Advice
If you are building an analytics capability for an industrial operation, start small and iterate. Pick one machine or one line that has a clear pain point, frequent unplanned downtime, high scrap rate, quality variability. Instrument it, stream the data through a simple event pipeline, and build one model or one dashboard that addresses that pain. Prove the value before you scale. I have seen too many teams try to boil the ocean with a grand data platform initiative that never delivers a single actionable insight.
Do not underestimate the cost of data governance. Every source system will have its own idea of what "temperature" means. Some will report Celsius, some Fahrenheit. Some will include the sensor's internal calibration offset, some will not. Building the transformation logic to make that consistent across the Unified Namespace takes time and careful testing. Automate as much of it as you can, but plan for manual intervention when a new sensor type or a new data source appears.
Finally, think about how your analytics will be used, not just how they will be built. A beautiful time-series chart of motor current is useless if the maintenance team does not know what threshold to act on. Work with the people who will use the output, operators, maintenance techs, plant managers, to define what a useful alert looks like. That seems obvious, but I have watched many teams build analytics in isolation and then wonder why nobody uses them.
The industrial shift toward smart factories and connected operations is not going to slow down. As more machines come online with more sensors, the volume and velocity of streaming data will only increase. The organisations that get ahead are not the ones with the most sophisticated machine learning models. They are the ones that build a solid, event-driven foundation for their operational data, and then put real-time analytics on top of it, not the other way around.